

From Raw Data to a Usable Dataset
Collected or supplied datasets can arrive with duplicate records, inconsistent formatting, missing values, mismatched field structures, or other inconsistencies. Before that information is useful, it needs to be cleaned and organized.
This service focuses on that step: taking a dataset as it exists and processing it into the structure a project actually needs, according to the rules defined for that project.
Request a Data Collection Project
What Data Cleaning Can Address
Depending on the dataset and the project’s requirements, cleaning can address issues such as:
- Duplicate records
- Inconsistent formatting
- Missing or incomplete values
- Inconsistent field values
- Unwanted characters or formatting
- Inconsistent naming or casing
- Other data-quality issues defined for the project
Which of these apply depends entirely on the condition of the dataset being processed.
Structuring Data for Its Intended Use
Cleaning removes the noise; structuring gives the remaining data a shape the project can actually use. A clean dataset still needs a defined structure before it’s ready to use. Depending on the requirement, this can include:
- Consistent columns and fields
- Normalized values
- Defined record structures
- Organized datasets
- Database-ready structures, where supported by the project
Cleaning and Structuring Workflow
The work generally moves through the same stages, adapted to the dataset and the project’s requirements:
- Dataset Receipt
- Field Definition
- Cleaning
- Normalization
- Structuring
- Validation
- Data Delivery
Working With Different Dataset Sources
The dataset going into this process doesn’t have to come from one place. It may originate from:
- Web data collection
- An existing dataset you already hold
- Files supplied directly by the client
- Other sources defined for the project
The cleaning and structuring rules are applied to the dataset regardless of where it originated.
What a Structured Dataset Can Look Like
Once processed, the result is a dataset defined by:
- Consistent fields
- Organized records
- Cleaned values
- A defined structure
- The output format required for the project
Common delivery formats include CSV, Excel, JSON, API, or database-ready output, depending on what the project calls for.
One-Time Cleaning and Ongoing Processing
One-Time Cleaning
A single dataset is cleaned, normalized, and structured once. This fits an existing dataset that simply needs to be put right before use, such as:
- Cleaning an existing dataset
- Duplicate removal
- Field normalization
- Formatting cleanup
- Restructuring a supplied dataset
Ongoing Processing
Where a dataset is refreshed on an ongoing basis, the same cleaning and structuring rules can be applied to each new batch, so the fields stay consistent from one round to the next.
From Raw Data to Business-Ready Structure
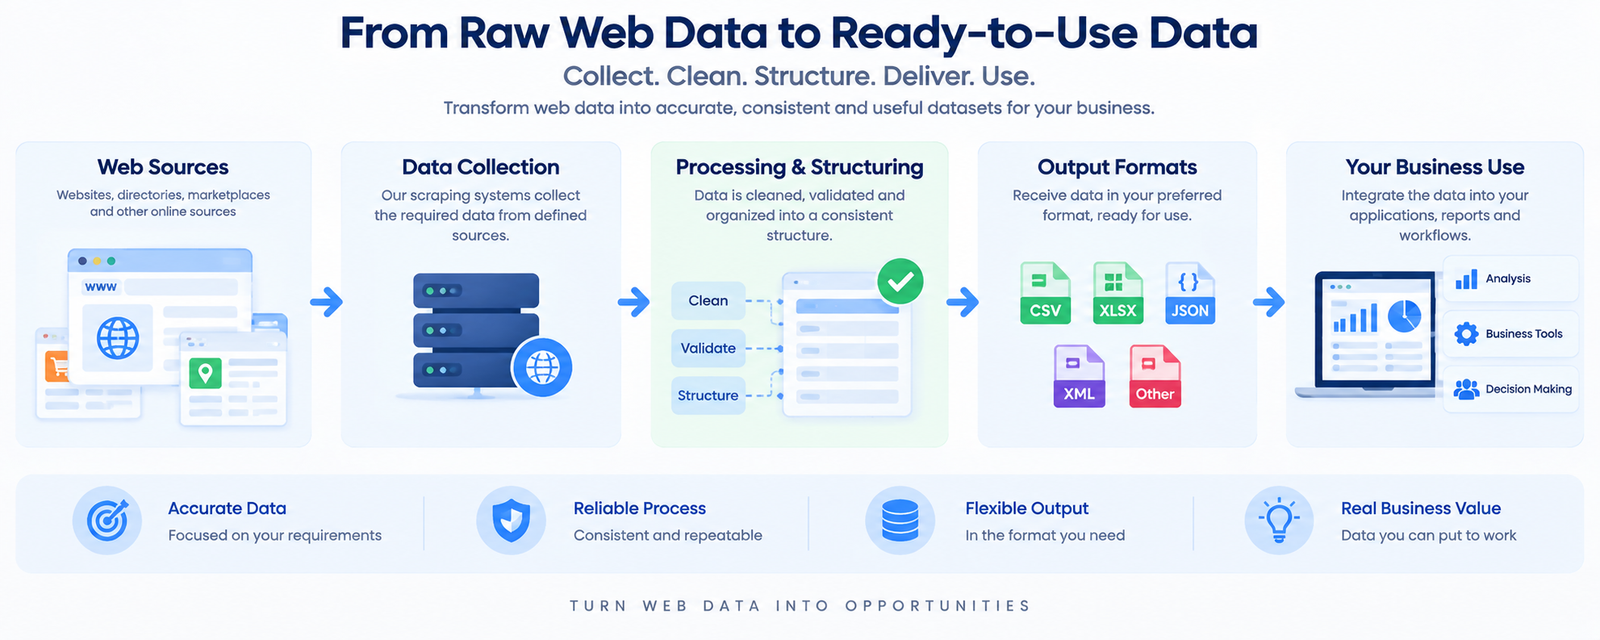
The diagram below illustrates that transformation: information starts out scattered and inconsistent, and moves through defined cleaning and structuring steps until it reaches a structure ready for the format your business needs.
When Data Cleaning & Structuring Is Useful
This service tends to fit situations where the data already exists but isn’t yet usable, such as:
- A dataset with duplicate records
- A dataset with inconsistent formats
- Data collected from multiple sources that don’t line up
- A supplied dataset that needs normalization
- A dataset that needs to be reshaped into a defined output structure
Where the data doesn’t exist yet and needs to be collected first, that falls under a collection project rather than this service.
Define the Dataset You Need Processed
Before scoping the work, it helps to define:
- The source dataset
- The fields it contains
- Required cleaning rules
- Normalization requirements
- The output structure needed
- The delivery format required
Once these are defined, we can review the dataset and confirm an approach for processing it.
Request a Data Collection Project